wisemonkeys logo
FeedNotificationProfileManage Forms
FeedNotificationSearchSign in
wisemonkeys logo

Blogs

Big Data Architecture

profile
Jermin Shaikh
Mar 14, 2022
0 Likes
0 Discussions
141 Reads

What is Big Data Architecture?

  • This architecture is designed in such a way that it handles the ingestion process, processing of data, and analysis of the data is done which is way too large or complex to handle the traditional database management systems.
  • Different organizations have different thresholds for their organizations, some have it for a few hundred gigabytes while for others even some terabytes are not good enough a threshold value.
  • Due to this event happening if you look at the commodity systems and the commodity storage the values and the cost of storage have reduced significantly. There is a huge variety of data that demands different ways to be catered.
  • Some of them are batch-related data that comes at a particular time and therefore the jobs are required to be scheduled similarly while some others belong to the streaming class where a real-time streaming pipeline has to be built to cater to all the requirements. All these challenges are solved by big data architecture.

Explanation of Big Data Architecture

Big Data Architecture Systems


Big Data systems involve more than one workload type and they are broadly classified as follows:

  1. Where the big data-based sources are at rest batch processing is involved.
  2. Big data processing is in motion for real-time processing.
  3. Exploration of interactive big data tools and technologies.
  4. Machine learning and predictive analysis.

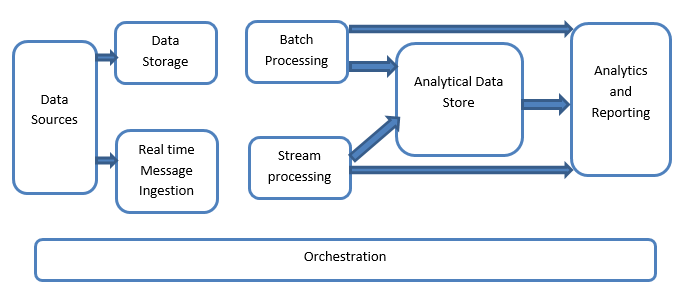
1. Data Sources

The data sources involve all those golden sources from where the data extraction pipeline is built and therefore this can be said to be the starting point of the big data pipeline.

The examples include:
(i) Datastores of applications such as the ones like relational databases

(ii) The files which are produced by several applications and are majorly a part of static file systems such as web-based server files generating logs.

(iii) IoT devices and other real-time-based data sources.

2. Data Storage

This includes the data which is managed for the batch-built operations and is stored in the file stores which are distributed in nature and are also capable of holding large volumes of different format-backed big files.

3. Batch Processing

All the data is segregated into different categories or chunks which makes use of long-running jobs used to filter and aggregate and also prepare data o a processed state for analysis. These jobs usually make use of sources, process them and provide the output of the processed files to the new files. The batch processing is done in various ways by making use of Hive jobs or U-SQL-based jobs or by making use of Sqoop or Pig along with the custom map reducer jobs which are generally written in any one of the Java or Scala or any other language such as Python.

4. Real Time-Based Message Ingestion

This includes, in contrast with the batch processing, all those real-time streaming systems which cater to the data being generated sequentially and in a fixed pattern. This is often a simple data mart or store responsible for all the incoming messages which are dropped inside the folder necessarily used for data processing. There are, however, the majority of solutions that require the need of a message-based ingestion store that acts as a message buffer and also supports the scale-based processing, providing a comparatively reliable delivery along with other messaging queuing semantics. The options include those like Apache Kafka, Apache Flume, Event hubs from Azure, etc.

5. Stream Processing

There is a slight difference between real-time message ingestion and stream processing. The former takes into consideration the ingested data which is collected at first and then is used as a publish-subscribe kind of tool. Stream processing, on the other hand, is used to handle all that streaming data which is occurring in windows or streams and then writes the data to the output sink. This includes Apache Spark, Apache Flink, Storm, etc.

6. Analytics-Based Datastore

This is the data store that is used for analytical purposes and therefore the already processed data is then queried and analyzed by using analytics tools that can correspond to the BI solutions. The data can also be presented with the help of a NoSQL data warehouse technology like HBase or any interactive use of a hive database which can provide the metadata abstraction in the data store. Tools include Hive, Spark SQL, Hbase, etc.

7. Reporting and Analysis

The insights have to be generated on the processed data and that is effectively done by the reporting and analysis tools which make use of their embedded technology and solution to generate useful graphs, analysis, and insights helpful to the businesses. Tools include Cognos, Hyperion, etc.

8. Orchestration

Big data-based solutions consist of data-related operations that are repetitive and are also encapsulated in the workflows which can transform the source data and also move data across sources as well as sinks and load in stores and push into analytical units. Examples include Sqoop, oozie, data factory, etc.

Comments ()


Sign in

Read Next

What is Spyware? and examples of them.

Blog banner

Soak knowledge and level up your intellectual potential!!!

Blog banner

Modern operating system

Blog banner

What is a Malware ?

Blog banner

Secure Hypertext transfer protocol

Blog banner

Data Lake

Blog banner

Python as a tool for Data science task & project

Blog banner

My Favorite Country

Blog banner

Whatsapp Messenger

Blog banner

How To Setup DVWA Using XAMPP on Windows

Blog banner

Power of words

Blog banner

Busted : Common Web Security Myths

Blog banner

MODERN OPERATING SYSTEM

Blog banner

Satellite Based Positioning

Blog banner

Direct Memory Access

Blog banner

objectives and functions of operating system

Blog banner

IT security management

Blog banner

GOOGLE

Blog banner

Man VS Nature

Blog banner

Direct Memory Access

Blog banner

Metasploit

Blog banner

Social Media.

Blog banner

PROCESS STATE:

Blog banner

Exploring the Power of Encase Forensic Tools: Unraveling Digital Mysteries

Blog banner

VIRTUAL MACHINES

Blog banner

Buffering

Blog banner

Kafka - A Framework

Blog banner

The Power of Forensic Watermarking in the Fight Against Content Piracy

Blog banner

File and File System Structure

Blog banner

Note Taker App

Blog banner

IoT Architecture Based Security

Blog banner

Memory Management

Blog banner

A-B-C of Networking: Part-3 (Topology [Ring, Tree, Mesh])

Blog banner

From Model Mistakes to Metrics

Blog banner

Hash password! Is it really secured?

Blog banner

My First Dream Bike

Blog banner

The Art of Slow Fashion: Why Patola Defines Sustainable Luxury

Blog banner

How return on investment is defined in IT services

Blog banner

Memory Management - operating system

Blog banner

Deadlock and Starvation

Blog banner

What is Password Cracking ? and it's Techniques.

Blog banner

What are Tenders its various types

Blog banner